I compared seven embedding models. The default won, because the model was not the problem
acp ask answers plain-English questions about my Claude Code usage. It matches the question to a catalog of tested SQL queries with a small local embedding model, all-MiniLM-L6-v2. I chose that model at first because it was lightweight and fast, but without running any benchmarks against other models. Then the
Asking my Claude usage data questions in plain English, without letting a model write SQL
Dashboards are great for a general visual overview, but what if we just want answers to specific questions as “How many tokens were spent per model?” The obvious answer today is to let a model write the SQL. I wanted to try a different local-first approach. So I created the
What would my Claude Code usage cost on the API?
Using Claude Code on a subscription means not paying per token. But I wanted to know: what would my usage cost on the API? The answer depends on which token count you trust. Same session, two token totals One API call can write several records to the transcript, one per
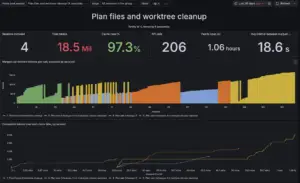
Four Grafana dashboards for my Claude Code usage
In my last post, I loaded three months of Claude Code transcripts into PostgreSQL. A database is good for questions you already have. Dashboards are good for the questions you did not think of. With the tool, four Grafana dashboards are built to answer questions regarding Claude Code token spending